MIT HAN Lab develops the algorithms and systems that make frontier AI practical. We work on reasoning models, generative video, multimodal AI, and embodied intelligence. Our approach is algorithm–system co-design: advancing model capabilities while reducing the cost of training and inference. From post-training and low-bit inference to long-context serving and real-time video, our research connects new ideas with working systems. Explore our projects for papers, open-source code, and demos, and see how efficient AI research reaches beyond the lab.
PI: Prof. Song Han
Alumni: Ji Lin (OpenAI -> Meta TBD lab), Hanrui Wang (Co-founder @Eigen AI, acquired by Nebius, SVP of applied AI), Zhijian Liu (Assistant professor @UCSD; co-founder @Inco AI), Han Cai (NVIDIA Research), Haotian Tang (Google Deepmind->Meta TBD lab), Yujun Lin (NVIDIA Research -> Co-founder @Nunchux AI), Wei-Chen Wang (Co-Founder @Eigen AI, acquired by Nebius, VP of AI Inference), Wei-Ming Chen (NVIDIA), Muyang Li (Co-founder @Nunchux AI), Zhekai Zhang (Co-founder @Nunchux AI), Guangxuan Xiao (Thinking Machines Lab), Qinghao Hu (Incoming Assistant professor @HKU; Inco AI)
Prospective PhD students: Help build the next generation of efficient AI. Explore our recent work on reasoning, generative models, and embodied intelligence, then apply through the official MIT application website. Due to the volume of inquiries, we cannot respond to individual application emails.
Explore the ideas, systems, and open-source work behind efficient AI [slides]:
Real-time perception and responsive robots
PEAR trains a reasoning model with reinforcement learning entirely in simulation to use real robots, without demonstrations. StreamingVLM enables real-time video understanding, while VLASH improves robot responsiveness and ForeAct adds visual foresight planning.
Low-bit inference for real-world deployment
AWQ, SmoothQuant, and QServe accelerate low-bit LLM inference. DeltaQuant and FourTune bring low-precision efficiency to diffusion inference and post-training.
Sparse Attention
SpAtten and XAttention reduce attention costs through pruning and block sparsity, while Radial Attention accelerates video generation with an O(n log n) sparse attention mask.
Longer context, practical serving costs
StreamingLLM and LServe reduce memory and computation with efficient attention, while Jet-Long extends context windows without retraining.
High-resolution images and interactive video
SANA enables efficient high-resolution image synthesis, LongLive supports interactive long-video generation, and DC-AE accelerates diffusion models through deep spatial compression.
Stronger reasoning, more efficient post-training
Lightning Weave and Lightning OPD 2.0 improve reasoning through efficient distillation, while Hide to Guide accelerates expert-guided reinforcement learning.


Kernel Design Agents (KDA) achieves 1st place in the MoE Track, 2nd place in the DSA Track, and 3rd place in the GDN Track at the MLSys 2026 FlashInfer Full-Agent Track!
HART has been highlighted by MIT news: AI tool generates high-quality images faster than state-of-the-art approaches!
🔥⚡ We release TinyChat 2.0, the latest version with significant advancements in prefilling speed of Edge LLMs and VLMs, 1.5-1.7x faster than the previous version of TinyChat. Please refer to our blog for more details.
DistriFusion is integrated in NVIDIA's TensorRT-LLM for distributed inference on high-resolution image generation.
🔥 NVIDIA TensorRT-LLM, AMD, Google Vertex AI, Amazon Sagemaker, Intel Neural Compressor, FastChat, vLLM, HuggingFace TGI, and LMDeploy adopt AWQ to improve LLM serving efficiency. Our AWQ models on HuggingFace has received over 6 million downloads.
Congrats on graduation! Cheers on the next move: Zhijian Liu: assistant professor at UCSD, Hanrui Wang: assistant professor at UCLA, Ji Lin: OpenAI, Han Cai: NVIDIA Research, Wei-Chen Wang (postdoc): Amazon, Wei-Ming Chen (postdoc): NVIDIA.
We show SmoothQuant can enable W8A8 quantization for Llama-1/2, Falcon, Mistral, and Mixtral models with negligible loss.
We supported VILA Vision Languague Models in AWQ & TinyChat! Check our latest demos with multi-image inputs!
StreamingLLM is integrated by HPC-AI Tech SwiftInfer to support infinite input length for LLM inference.
StreamingLLM is integrated by CMU, UW, and OctoAI, enabling endless and efficient LLM generation on iPhone!
Congrats Ji Lin completed and defended his PhD thesis: "Efficient Deep Learning Computing: From TinyML to Large Language Model". Ji joined OpenAI after graduation.
AWQ is integrate by NVIDIA TensorRT-LLM, can fit Falcon-180B on a single H200GPU with INT4 AWQ, and 6.7x faster Llama-70B over A100.
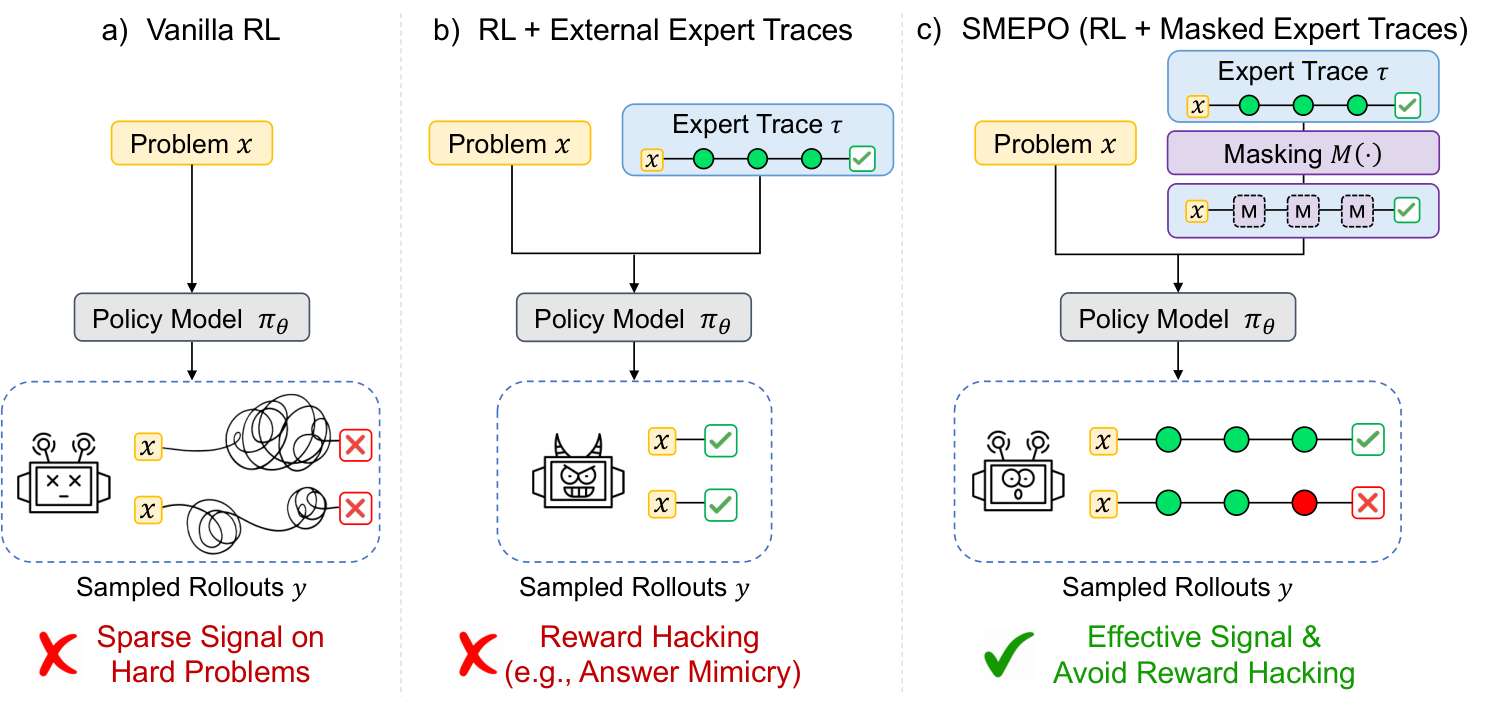
Reinforcement learning with verifiable rewards (RLVR) has become a powerful paradigm for improving language models on reasoning-intensive tasks, but its effectiveness is often limited by exploration. For example, models often fail on hard problems, leaving little useful reward signal. External expert traces offer a natural source of guidance, yet they may also expose reward-relevant content along the critical path to the verifier target, such as final answers, intermediate values, executable implementations, or answer-related entities. This content can create an unintended reward hacking channel, allowing the policy to obtain reward by copying the trace rather than learning the underlying reasoning or agentic behavior. Existing guided-RL methods reduce this risk by using partial trajectories, but they mainly control how much expert information is shown heuristically rather than which parts should be hidden. To this end, we propose Semantic Masked Expert Policy Optimization (SMEPO), a fine-grained semantic masking strategy for expert-guided RLVR. Instead of truncating traces coarsely or revealing them unchanged, SMEPO masks reward-relevant semantic spans along the critical path while preserving the expert's decomposition, plan, and procedural structure. This turns hard problems from reasoning from scratch into a fill-in-the-blank process: the policy can follow the expert's problem-solving route, but must still reconstruct the missing values, code, or entities by itself. SMEPO is simple to apply and requires no changes to the reward function or RL objective. Across diverse domains, including math, code, and agentic search, SMEPO improves accuracy by up to 3.2 points over GRPO and reduces training time by up to 4.2x. The code is available at https://github.com/mit-han-lab/SMEPO.
SMEPO is an expert-guided RLVR method that masks reward-relevant semantic spans in expert traces while preserving their plan and procedural structure, turning hard problems into a fill-in-the-blank process. It improves accuracy by up to 3.2 points over GRPO and cuts training time by up to 4.2x.
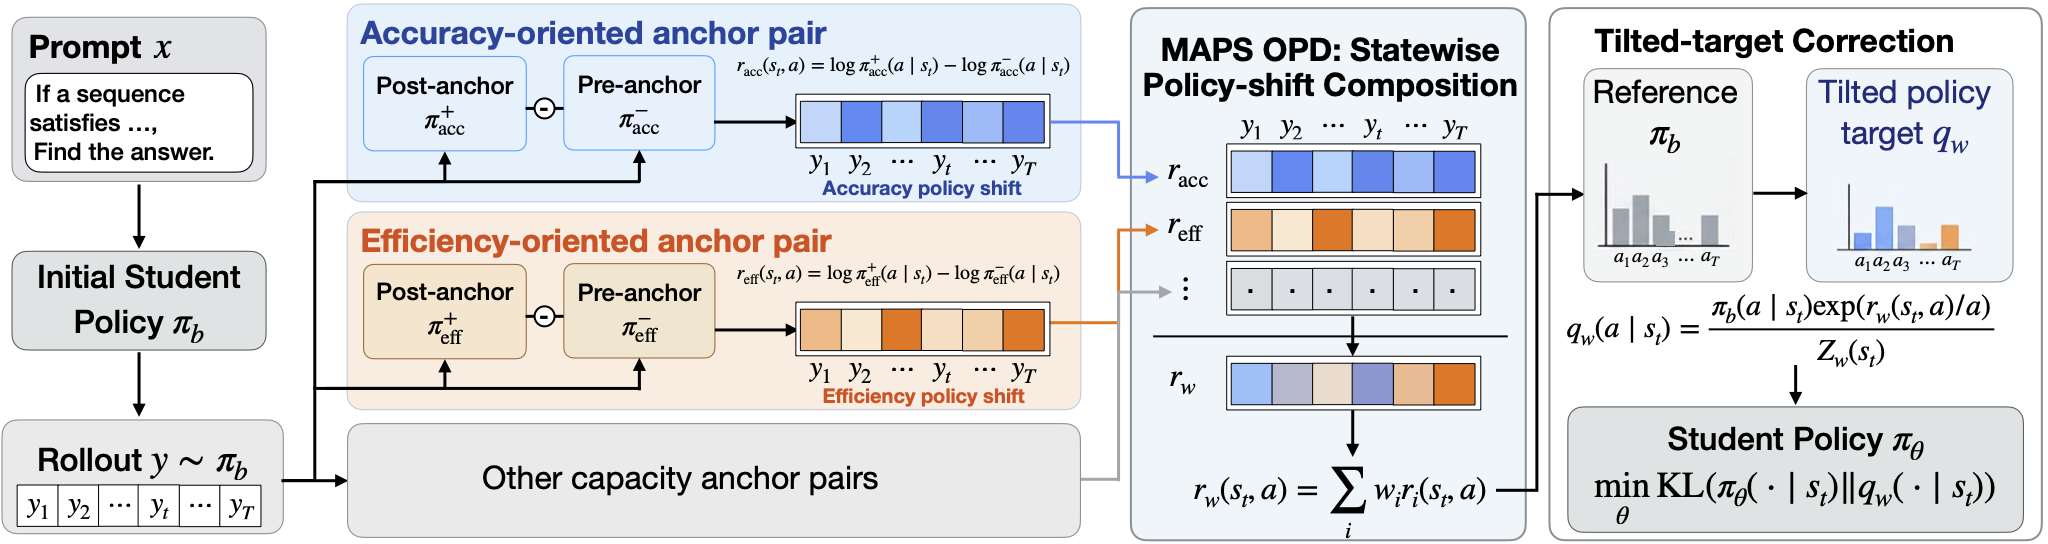
A core goal of efficient reasoning is to improve the accuracy-efficiency frontier. However, jointly improving reasoning accuracy and inference efficiency can be challenging, as the two objectives can favor different reasoning behaviors. Independently post-trained models already offer distinct strengths in accuracy and efficiency. We introduce Lightning Weave, a post-training framework that extracts and composes these independently learned capabilities in a single student through on-policy distillation. Each acquired capability is represented by the policy shift from the model before post-training to the resulting specialist. Lightning Weave combines aligned log-ratio shifts at shared student token states and uses Tilted-Target DOPD to convert the cached signals into a stable learning target. Each anchor pair scores the cached trajectories once, enabling subsequent student training without serving multiple live anchor models concurrently. Across diverse student models and benchmarks in mathematics and code, Lightning Weave substantially improves upon the base students and achieves a state-of-the-art accuracy-efficiency frontier. On Qwen3.5-4B, it raises HMMT 2025 accuracy from 59.2% to 64.0% with 10.7% fewer response tokens, and LiveCodeBench v5 accuracy from 41.7% to 54.2% with 9.6% fewer response tokens. Adjusting the relative strengths of the anchor signals yields a strong empirical accuracy-efficiency Pareto frontier. These results establish Lightning Weave as a new practical route to efficient reasoning through capability composition.
Lightning Weave improves the accuracy-efficiency frontier of large reasoning models by composing capabilities from accuracy- and efficiency-oriented teachers into a single student through offline distillation.
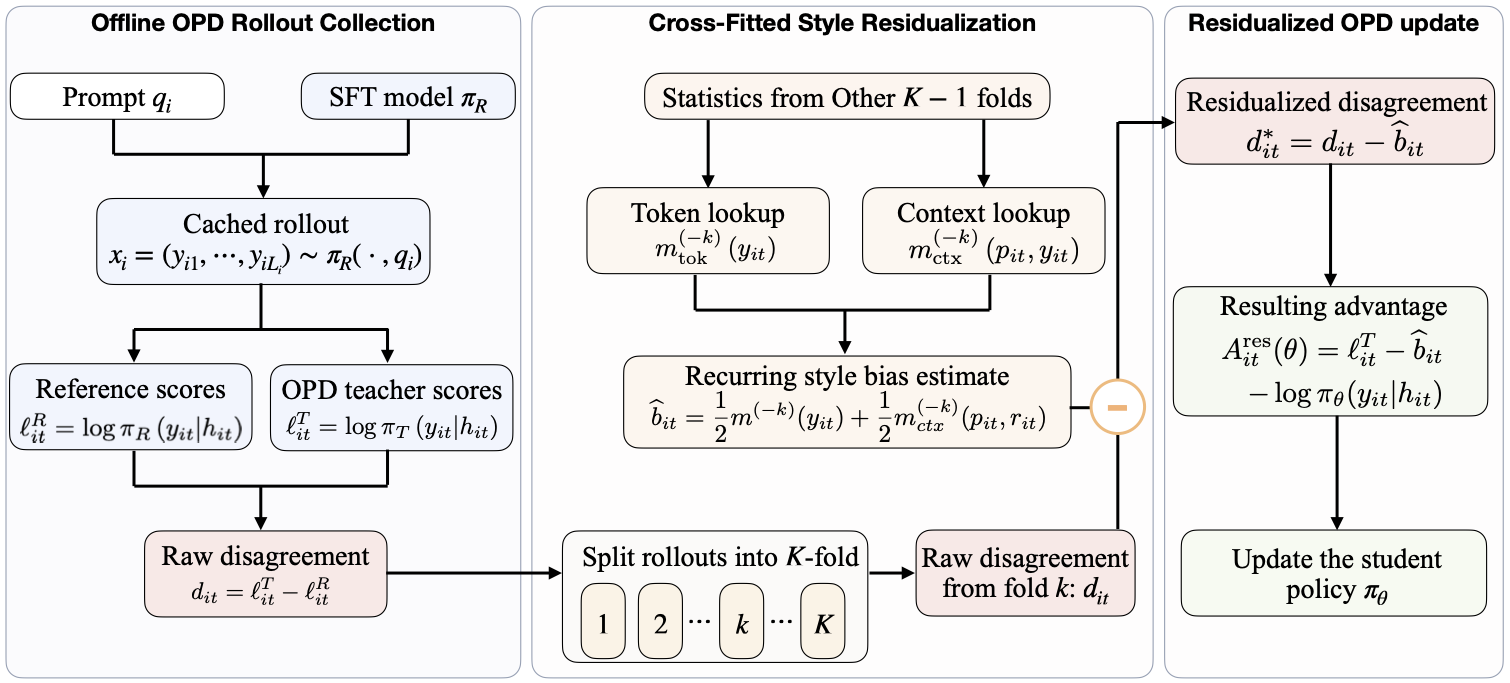
On-policy distillation (OPD) provides dense token-level supervision from a teacher, but its effectiveness can depend on teacher consistency, meaning that the model providing OPD supervision should also have generated the demonstrations used to train the supervised fine-tuning (SFT) reference. However, this condition is frequently violated in practice when SFT data have mixed or unknown provenance or when different models are preferred for SFT data generation and subsequent distillation. In such cross-teacher settings, even a stronger OPD teacher can yield little improvement over the SFT reference. We find that raw teacher--reference disagreement contains potentially useful context-specific teacher evidence as well as a recurring component associated with differences in wording, formatting, and reasoning cadence. We introduce Lightning OPD 2.0 with cross-fitted style residualization, which uses rollout-level cross-fitting to estimate this recurring component as an operational proxy for style-token bias and subtracts it before constructing the token-level OPD update. Across mathematical reasoning and code generation benchmarks, Lightning OPD 2.0 consistently outperforms Lightning OPD in cross-teacher settings. Starting from Klear-Reasoner-8B-SFT, Lightning OPD 2.0 reaches 82.4% on AIME 2024 and 63.0% on LiveCodeBench v5. Together, these results establish Lightning OPD 2.0 as a practical approach to cross-teacher OPD, relaxing teacher consistency as a prerequisite and allowing the SFT data generator and distillation teacher to be selected independently.
Lightning OPD 2.0 enables effective cross-teacher on-policy distillation by mitigating style bias through cross-fitted residualization, allowing the SFT data generator and distillation teacher to be chosen independently.
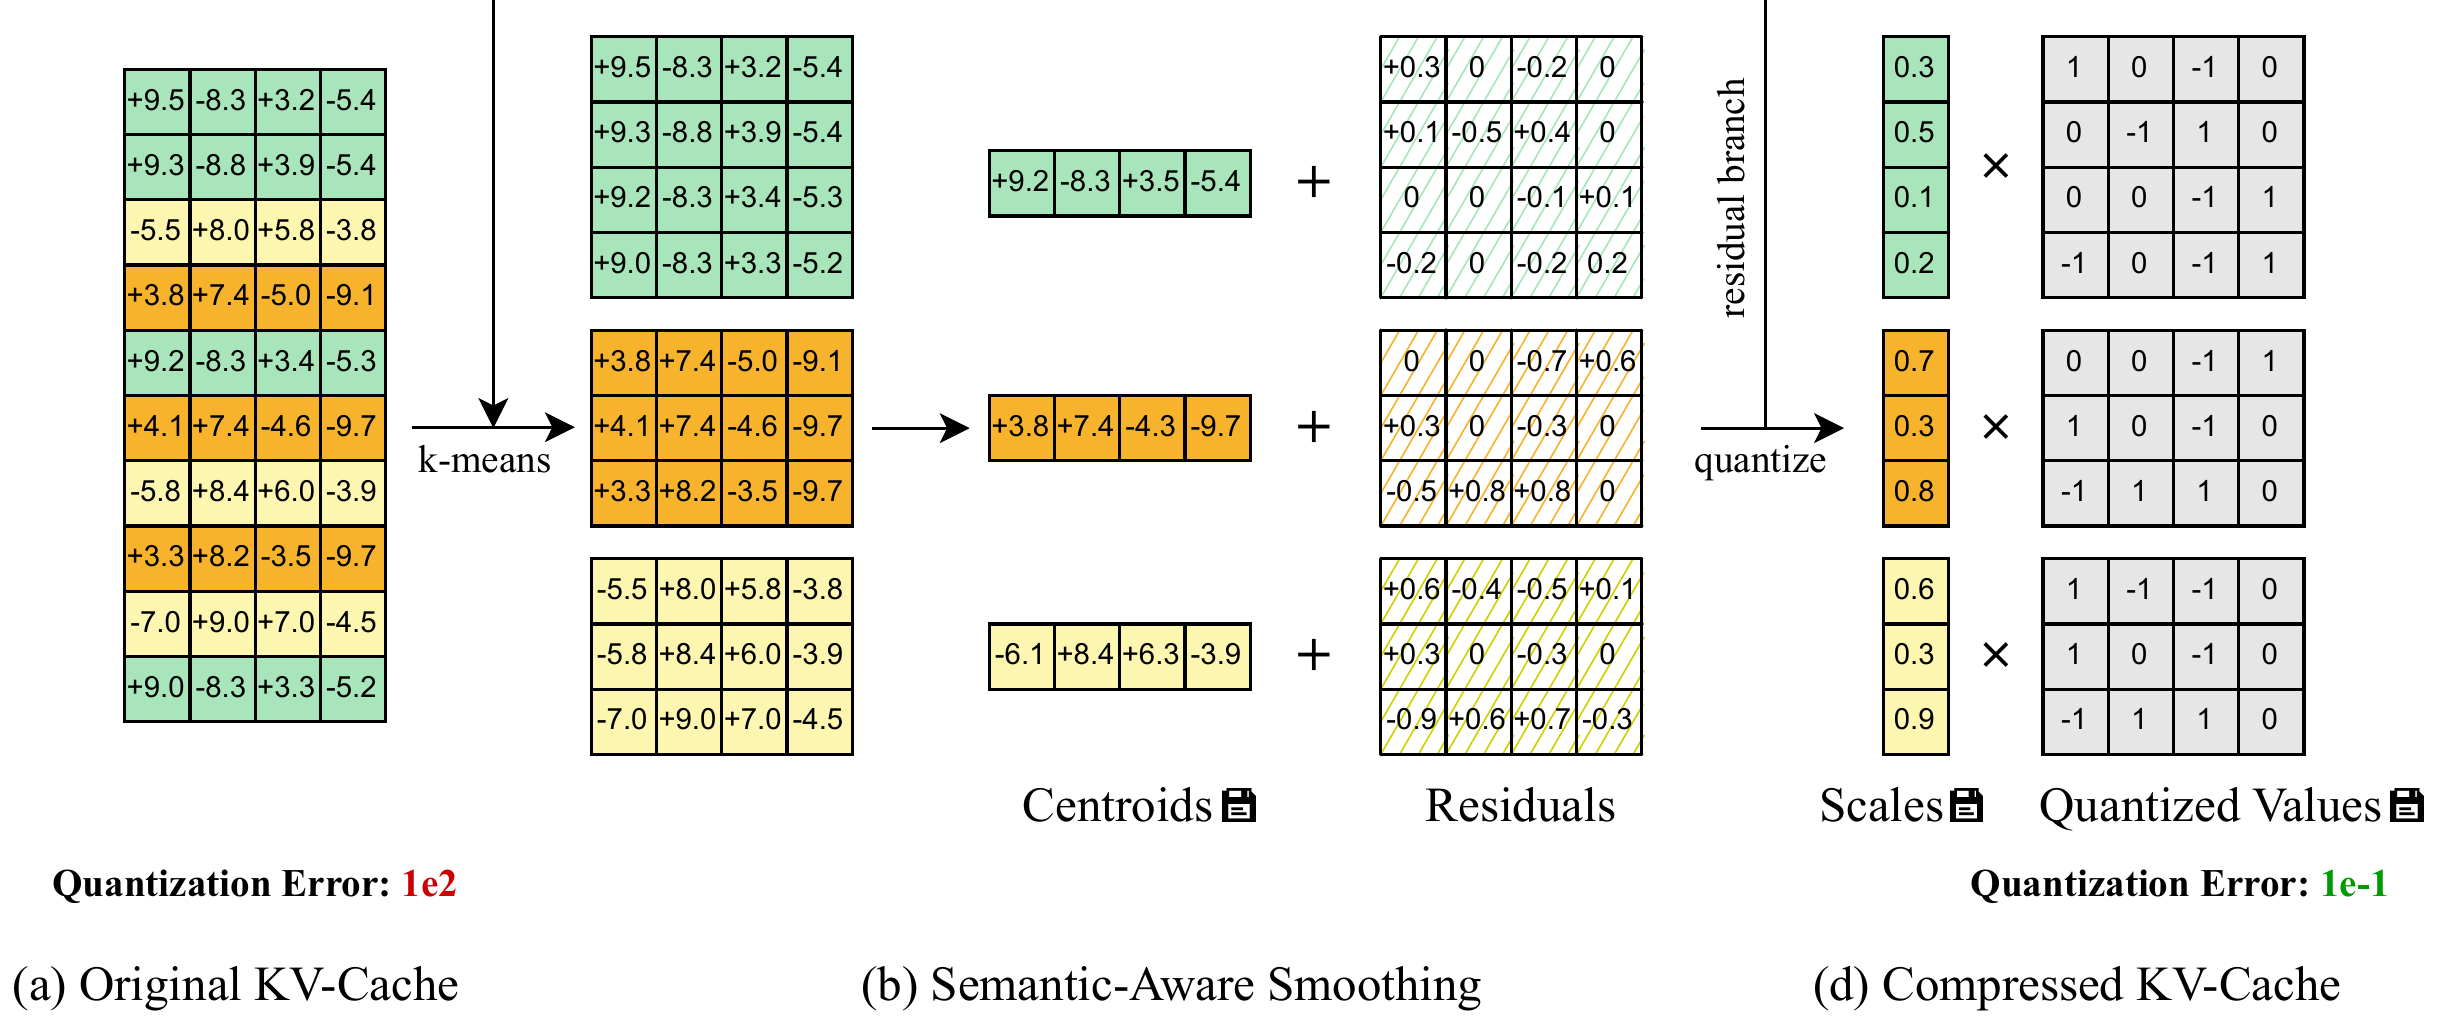
Despite rapid progress in auto-regressive video diffusion, we identify an emerging system–algorithm bottleneck that limits both deployability and capability: KV-cache memory. In auto-regressive video generation models, the KV-cache grows with history and rapidly dominates GPU memory (often ≥ 30 GB), blocking deployment on widely available hardware. More importantly, memory-bounded KV budgets force small working memory, which directly degrades long-horizon consistency in identity, layout, and motion, etc. To bridge this gap, we present Quant VideoGen (QVG), a training-free KV-cache quantization framework for auto-regressive video diffusion model. QVG exploits video’s spatiotemporal redundancy through Semantic-Aware Smoothing to produce low-magnitude, quantization-friendly residuals. QVG further propose Progressive Residual Quantization, a coarse-to-fine multi-stage scheme that reduces quantization error while enabling a smooth quality–memory trade-off. Across LongCat-Video, HY-WorldPlay, and Self-Forcing, QVG establishes a new Pareto quality-memory frontier, reducing KV memory by up to 7.0× with < 4% end-to-end latency overhead and significantly better quality over baselines.
A training-free KV-cache quantization framework for auto-regressive video diffusion, cutting KV memory by up to 7.0× with under 4% end-to-end latency overhead.
Efficient AI creates value when it works beyond the paper. Our research in model compression, inference, and acceleration has influenced or been adopted in AI software and hardware, including NVIDIA TensorRT-LLM, Intel Neural Compressor, and PyTorch. Industry teams can explore the projects and code above to evaluate the ideas for their own workloads. For founders and investors, our research and alumni offer a view into how efficient AI can become new tools, teams, and ventures. For research collaboration inquiries, contact hanlab@mit.edu.


