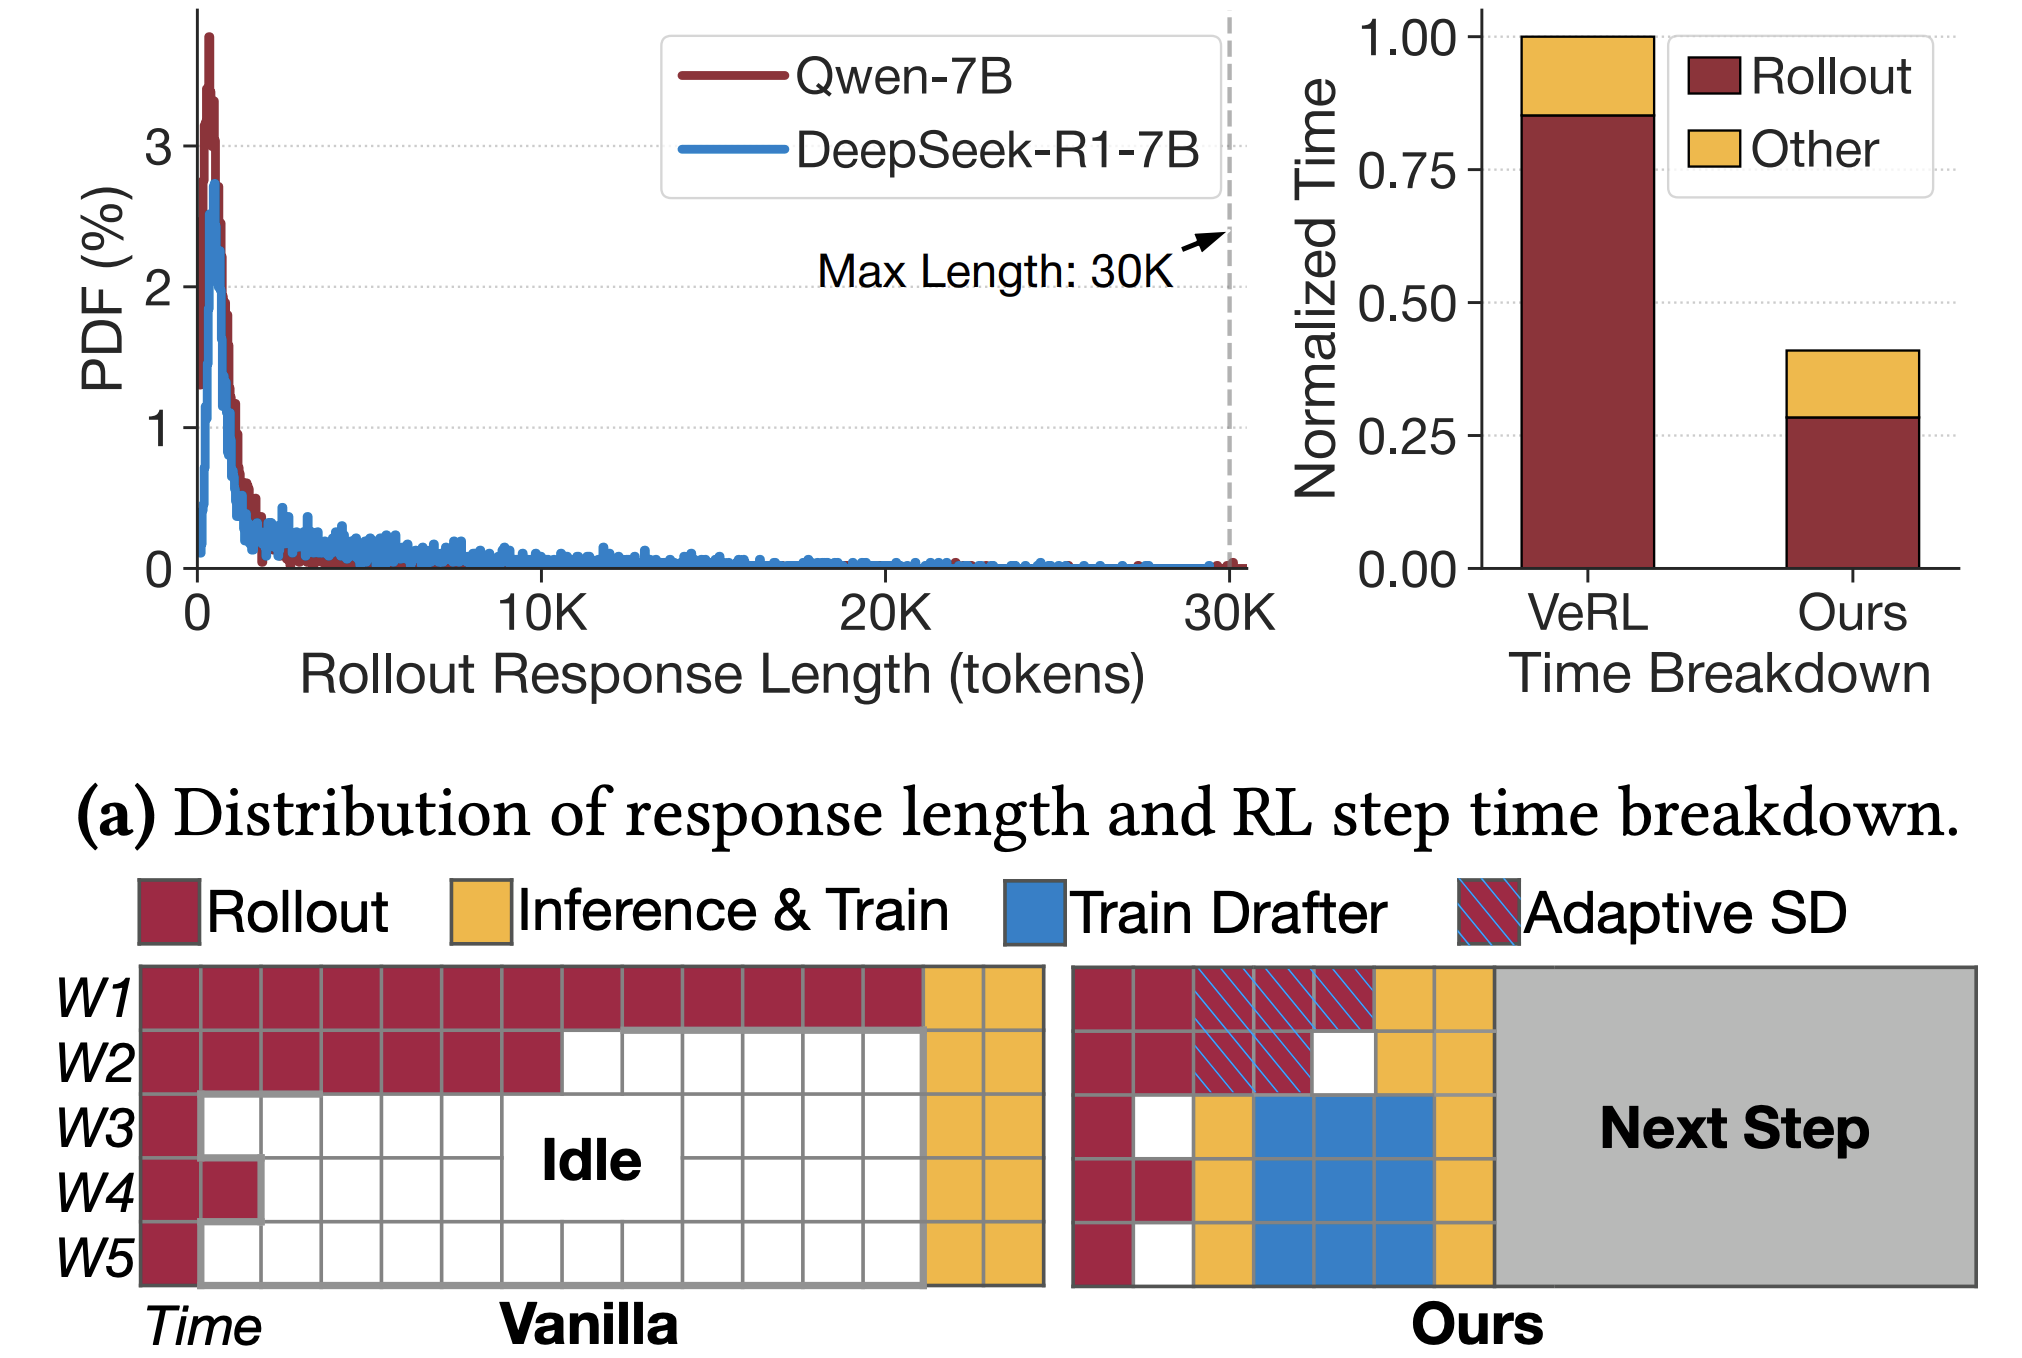
TLT is a lossless acceleration framework for reasoning-oriented LLM RL training, introducing adaptive speculative decoding to eliminate long-tail generation bottlenecks. It achieves over 1.7× end-to-end speedup while fully preserving model quality and producing a high-quality draft model for efficient deployment.