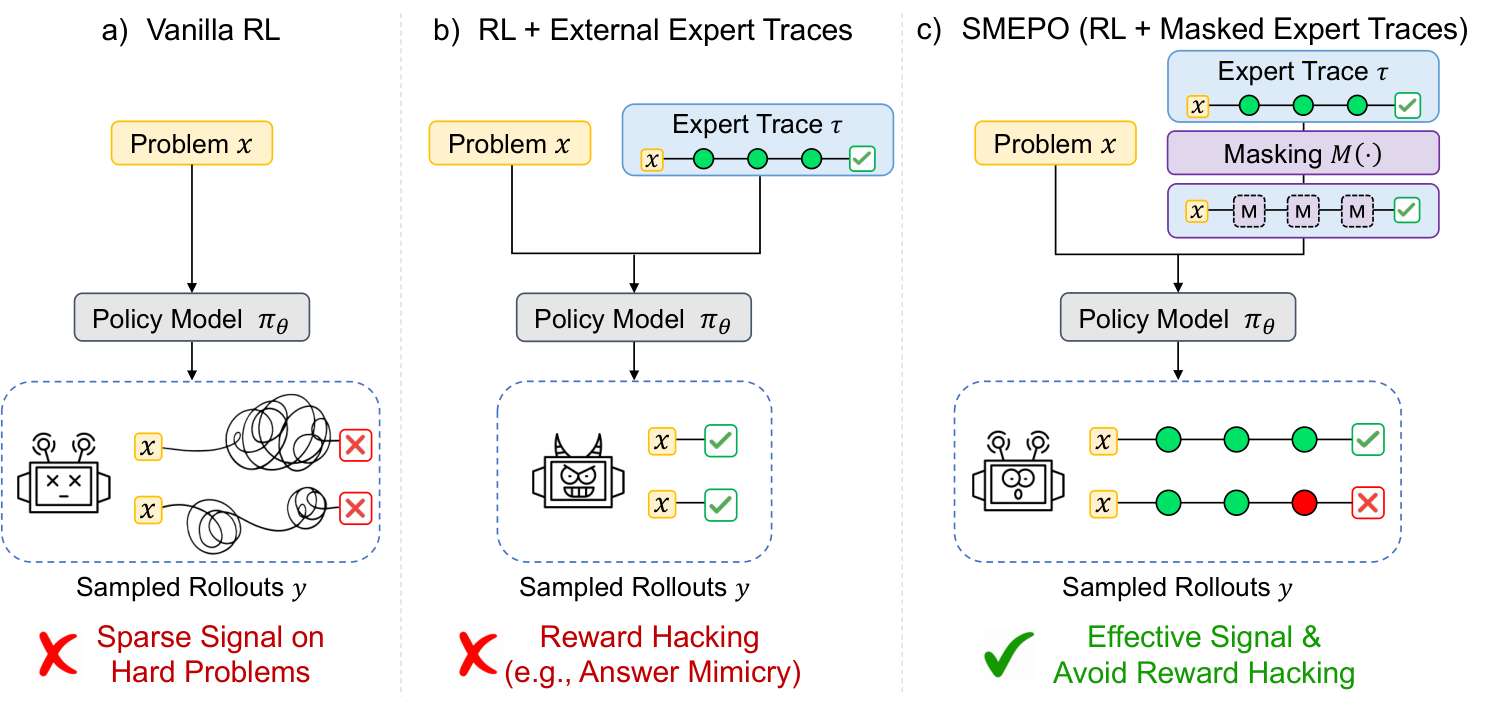
SMEPO is an expert-guided RLVR method that masks reward-relevant semantic spans in expert traces while preserving their plan and procedural structure, turning hard problems into a fill-in-the-blank process. It improves accuracy by up to 3.2 points over GRPO and cuts training time by up to 4.2x.
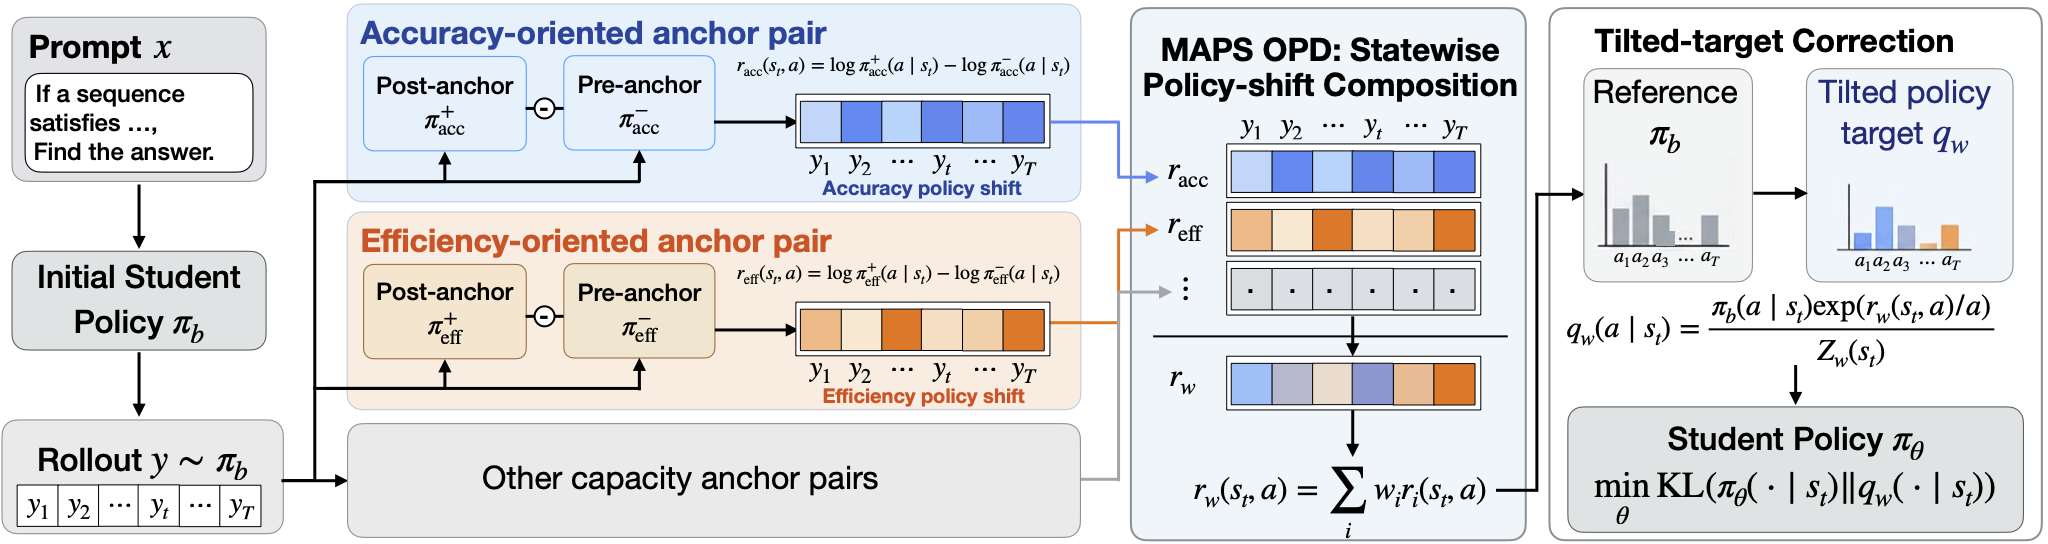
Lightning Weave improves the accuracy-efficiency frontier of large reasoning models by composing capabilities from accuracy- and efficiency-oriented teachers into a single student through offline distillation.
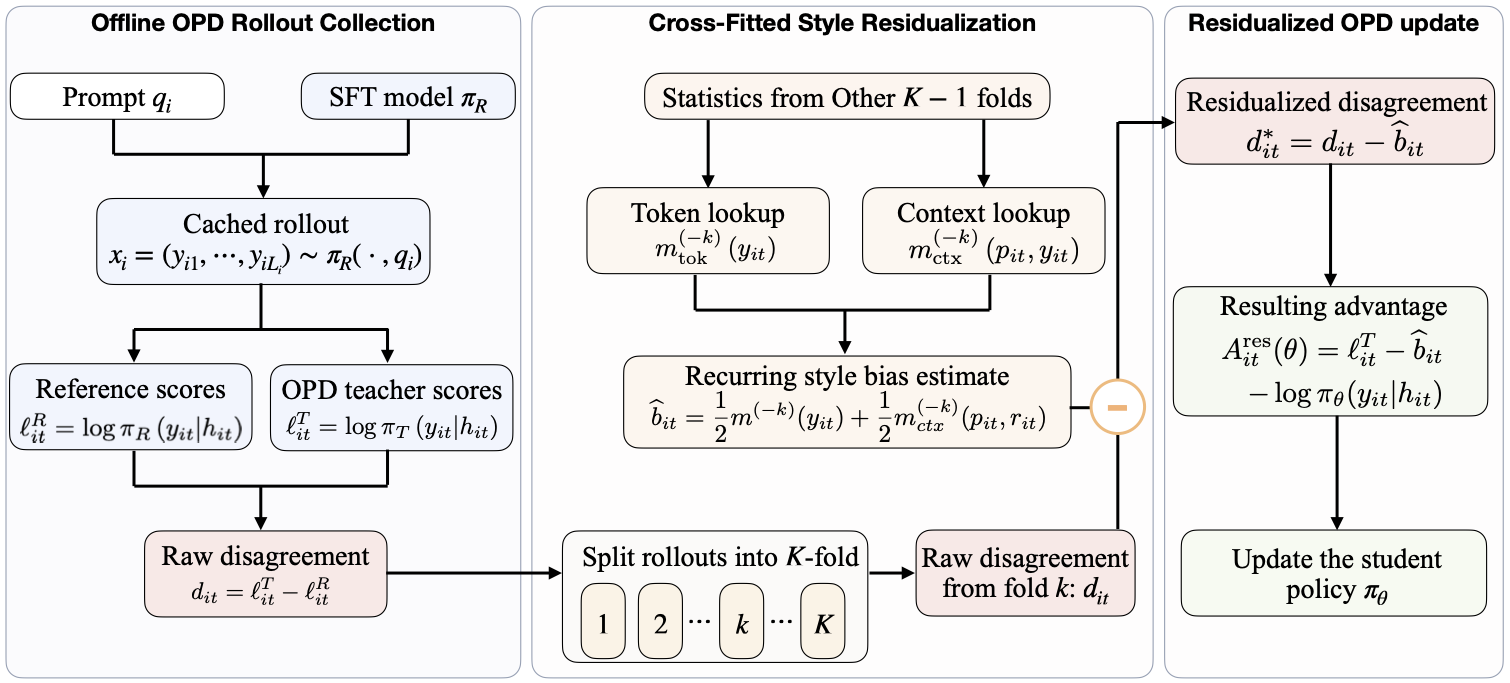
Lightning OPD 2.0 enables effective cross-teacher on-policy distillation by mitigating style bias through cross-fitted residualization, allowing the SFT data generator and distillation teacher to be chosen independently.
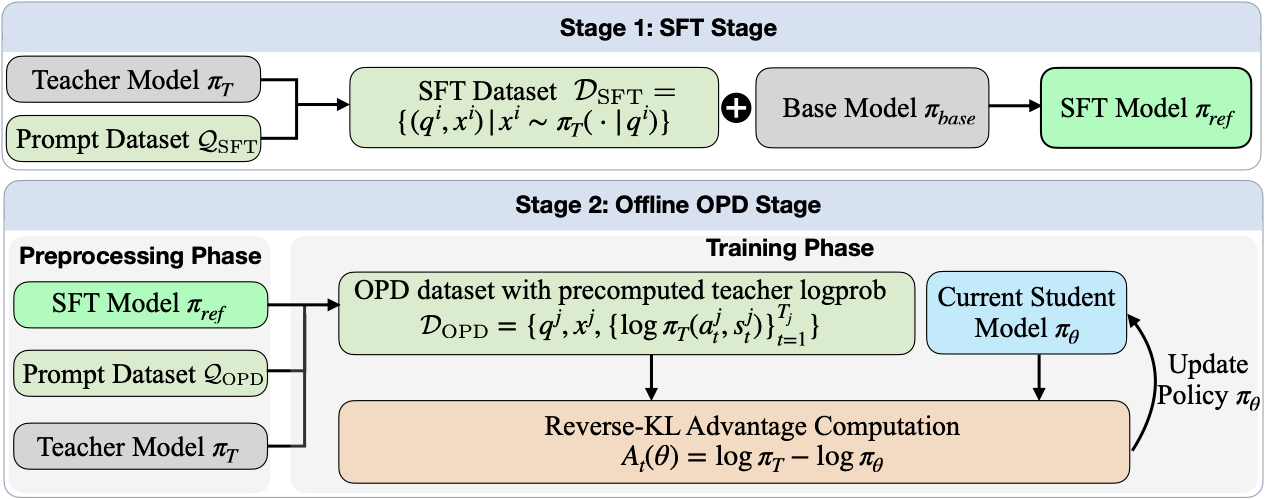
An offline post-training method for Large Reasoning Models that eliminates the need for live teacher during on-policy distillation, achieving a 4.0x higher training speedup while maintaining state-of-the-art performance.
QeRL is a framework that accelerates LLM training by combining NVFP4 quantization with LoRA. It reduces memory overhead, allows 32B model training on a single H100 GPU, and improves performance by leveraging quantization noise to
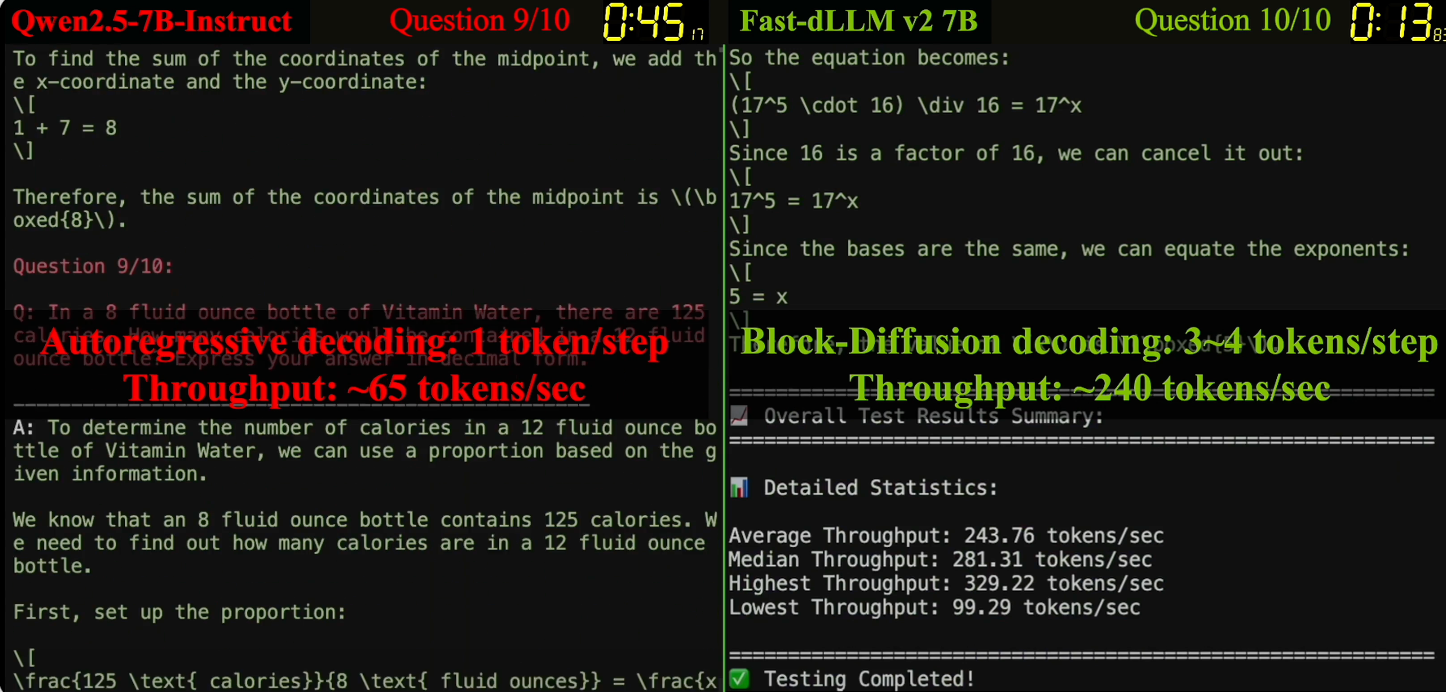
Our approach introduces a novel training recipe that combines a block diffusion mechanism with a complementary attention mask, enabling blockwise bidirectional context modeling without sacrificing AR training objectives.