

Vision-Language-Action models (VLAs) are becoming increasingly capable across diverse robotic tasks. However, their real-world deployment remains slow and inefficient: demonstration videos are often sped up by 5-10x to appear smooth, with noticeable action stalls and delayed reactions to environmental changes. Asynchronous inference offers a promising solution to achieve continuous and low-latency control by enabling robots to execute actions and perform inference simultaneously. However, because the robot and environment continue to evolve during inference, a temporal misalignment arises between the prediction and execution intervals. This leads to significant action instability, while existing methods either degrade accuracy or introduce runtime overhead to mitigate it. We propose VLASH, a general asynchronous inference framework for VLAs that delivers smooth, accurate, and fast reaction control without additional overhead or architectural changes. VLASH estimates the future execution-time state by rolling the robot state forward with the previously generated action chunk, thereby bridging the gap between prediction and execution. Experiments show that VLASH achieves up to 2.03x speedup and reduces reaction latency by up to 17.4x compared to synchronous inference while fully preserving the original accuracy. Moreover, it empowers VLAs to handle fast-reaction, high-precision tasks such as playing ping-pong and playing whack-a-mole, where traditional synchronous inference fails.
VLASH is a general asynchronous inference framework for VLAs that delivers smooth, accurate, and low-latency control with no overhead or architectural changes. By rolling the robot state forward with the previous action chunk, it achieves up to 2.03× speedup and 17.4× lower reaction latency while fully preserving accuracy.
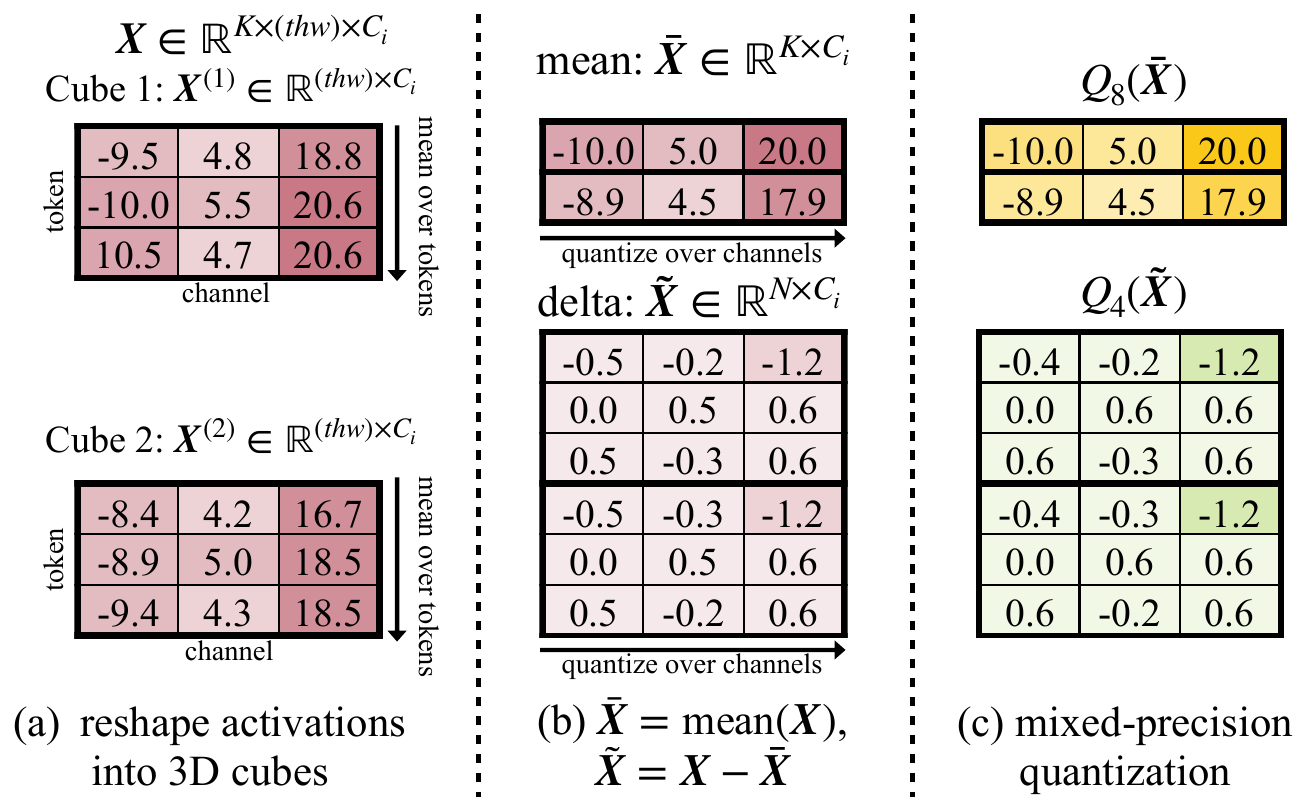
Video diffusion models have achieved remarkable generative performance, but their substantial computational and memory costs pose significant challenges for deployment, especially on consumer GPUs. As recent advances in attention optimization mitigate previous computational bottlenecks, linear layers now dominate both computational cost and inference memory. In this work, we focus on quantizing both weights and activations to 4 bits to accelerate these layers. Previous methods, such as SVDQuant, overlook the highly dynamic nature of activations across denoising timesteps, where outlier channels and magnitudes vary dramatically. However, video data inherently exhibits strong activation similarity among neighboring tokens in space and time, which we term spatiotemporal activation similarity, analogous to how video codecs exploit intra- and inter-frame redundancy. Leveraging this property, we introduce DeltaQuant, which partitions activations into local 3D spatiotemporal cubes and uses each cube's mean token as a core token, quantizing only the small differences (delta tokens) to 4 bits while keeping core tokens in FP8. This decomposition substantially reduces quantization error with minimal overhead. For weight quantization, DeltaQuant incorporates SVDQuant's low-rank decomposition to further reduce quantization error. We also implement an efficient kernel that translates DeltaQuant's computational benefits into real-world speedups. Extensive experiments on Wan 2.2 I2V, Wan 2.2 T2V, and LTX-Video T2V demonstrate that DeltaQuant maintains high generation fidelity. On Wan 2.2, it compresses model size by 2.9x and reduces memory footprint by 2.3x. DeltaQuant is compatible with efficient attention mechanisms and few-step distillation. When integrated with these techniques, it achieves an additional 3.0x acceleration, for a total 111.8x end-to-end speedup. Code and models will be released upon publication.
A 4-bit weight-activation quantization method for video diffusion models that exploits spatiotemporal activation similarity, compressing Wan 2.2 by 2.9× and cutting memory by 2.3×.
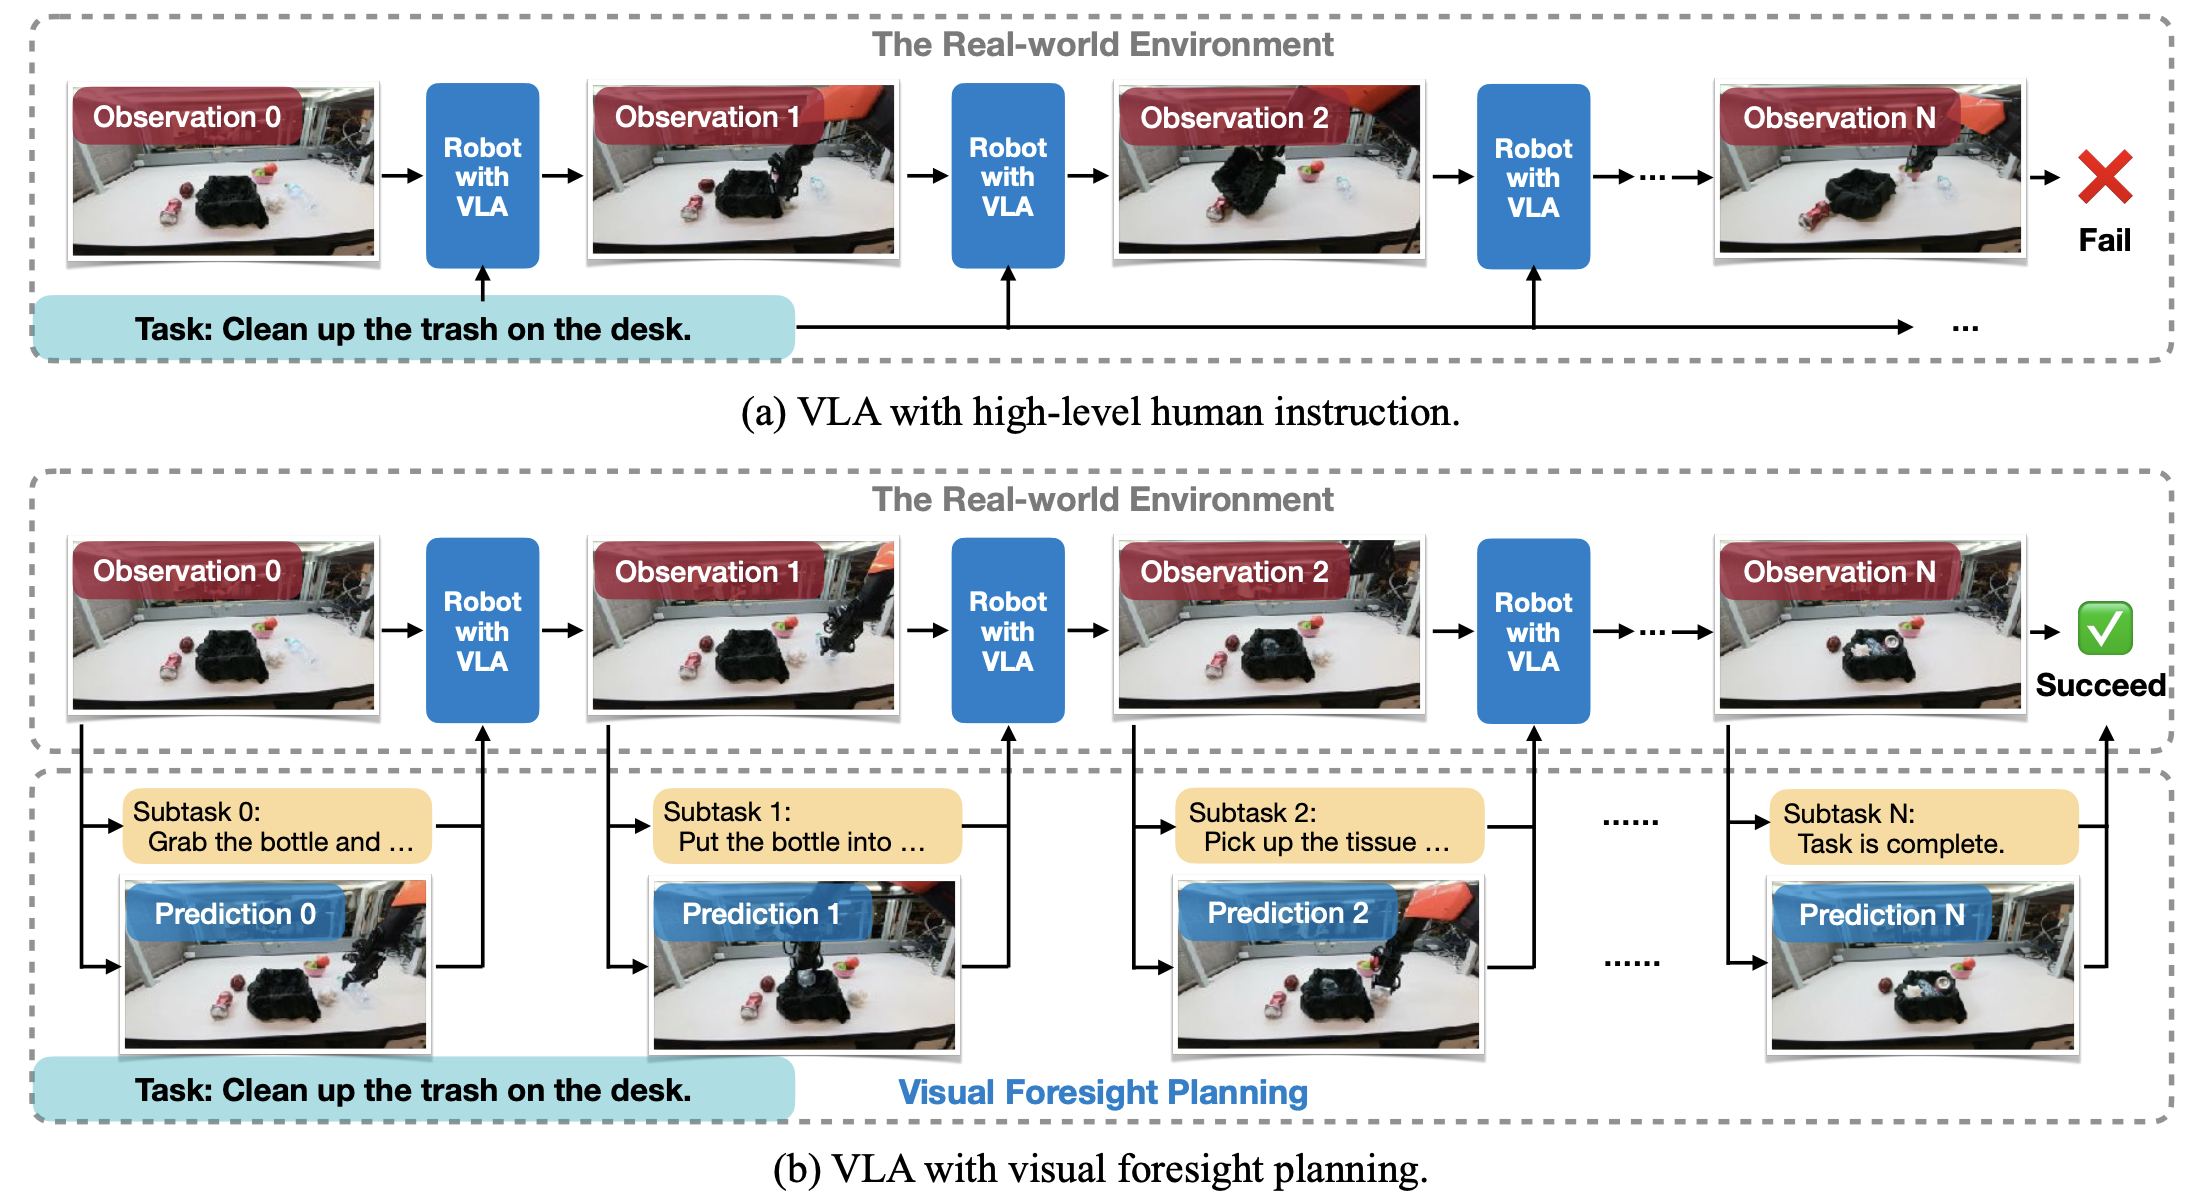
Vision-Language-Action (VLA) models convert high-level language instructions into concrete, executable actions, a task that is especially challenging in open-world environments. We present Visual Foresight Planning (ForeAct), a general and efficient planner that guides a VLA step-bystep using imagined future observations and subtask descriptions. With an imagined future observation, the VLA can focus on visuo-motor inference rather than high-level semantic reasoning, leading to improved accuracy and generalization. Our planner comprises a highly efficient foresight image generation module that predicts a high-quality 640×480 future observation from the current visual input and language instruction within only 0.33s on an H100 GPU, together with a vision-language model that reasons over the task and produces subtask descriptions for both the generator and the VLA. Importantly, state-of-the-art VLAs can integrate our planner seamlessly by simply augmenting their visual inputs, without any architectural modification. The foresight generator is pretrained on over 1 million multi-task, cross-embodiment episodes, enabling it to learn robust embodied dynamics. We evaluate our framework on a benchmark that consists of 11 diverse, multi-step realworld tasks. It achieves an average success rate of 87.4%, demonstrating a +40.9% absolute improvement over the π0 baseline (46.5%) and a +30.3% absolute improvement over π0 augmented with textual subtask guidance (57.1%).
ForeAct is a plug-and-play visual foresight planner that enables state-of-the-art VLAs to anticipate high-fidelity future observations for improved decision-making, generating 640×480 predictions in just 0.33s on a single H100 GPU without any architectural changes.
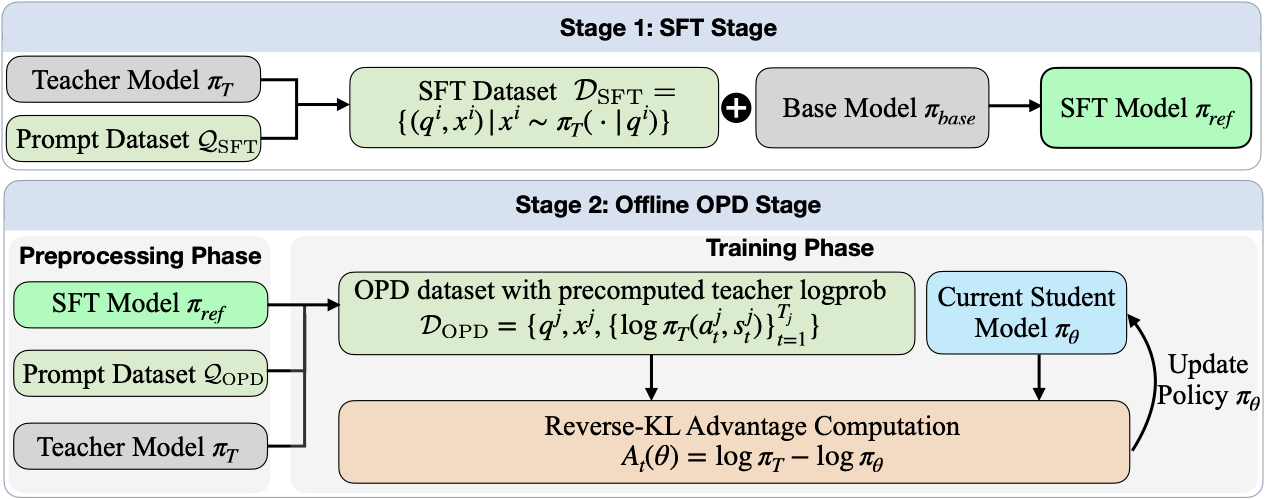
On-policy distillation (OPD) is an effective post-training paradigm for large language models but requires a live teacher server throughout training, resulting in substantial infrastructure overhead. We investigate whether OPD can be performed offline by precomputing teacher log-probabilities once over SFT rollouts and reusing them during training. We find that naively doing so fails to reliably match standard OPD, and trace the root cause to a previously overlooked condition we term teacher consistency, requiring that the same teacher be used for both supervised fine-tuning and OPD. Violating this condition introduces a gradient bias that degrades performance for both offline and online OPD. Building on this insight, we propose Lightning OPD, an offline on-policy distillation framework that enforces teacher consistency and eliminates the need for a live teacher server entirely. We prove that, under teacher consistency, Lightning OPD shares the same optimum as standard OPD, with bounded gradient discrepancy and an implicit regularization effect that helps prevent policy drift. Experiments on math reasoning and code generation show that Lightning OPD achieves comparable performance to standard OPD while delivering 4.0x higher training efficiency. Starting from an SFT-initialized Qwen3-8B-Base model, Lightning OPD reaches 69.9% on AIME 2024 in just 30 GPU hours. Lightning OPD further scales to MoE architectures, training Qwen3-30B-A3B to 71.0% on AIME 2024 on a single 8xH100 node, substantially lowering the barrier for academic research on LLM post-training.
An offline post-training method for Large Reasoning Models that eliminates the need for live teacher during on-policy distillation, achieving a 4.0x higher training speedup while maintaining state-of-the-art performance.


