
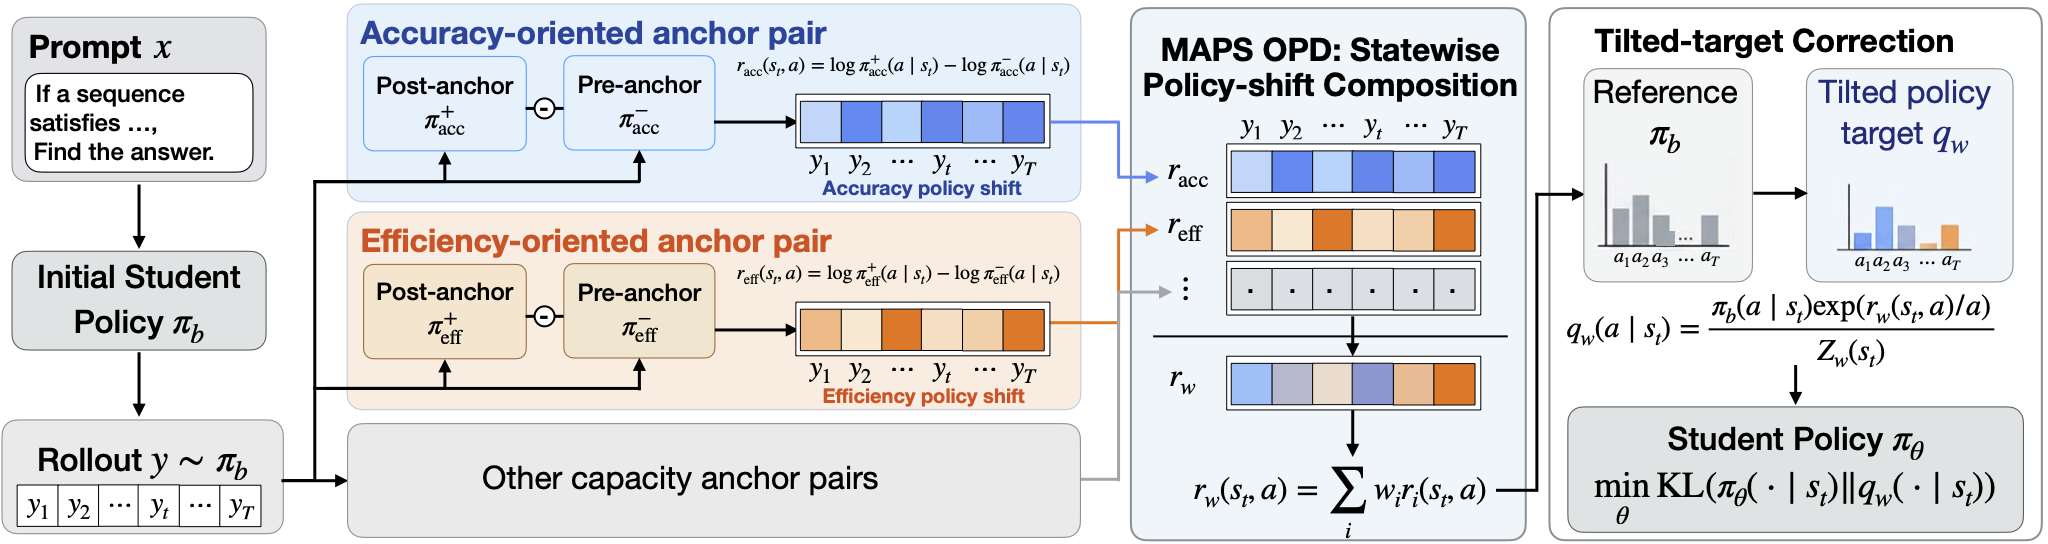
A core goal of efficient reasoning is to improve the accuracy-efficiency frontier. However, jointly improving reasoning accuracy and inference efficiency can be challenging, as the two objectives can favor different reasoning behaviors. Independently post-trained models already offer distinct strengths in accuracy and efficiency. We introduce Lightning Weave, a post-training framework that extracts and composes these independently learned capabilities in a single student through on-policy distillation. Each acquired capability is represented by the policy shift from the model before post-training to the resulting specialist. Lightning Weave combines aligned log-ratio shifts at shared student token states and uses Tilted-Target DOPD to convert the cached signals into a stable learning target. Each anchor pair scores the cached trajectories once, enabling subsequent student training without serving multiple live anchor models concurrently. Across diverse student models and benchmarks in mathematics and code, Lightning Weave substantially improves upon the base students and achieves a state-of-the-art accuracy-efficiency frontier. On Qwen3.5-4B, it raises HMMT 2025 accuracy from 59.2% to 64.0% with 10.7% fewer response tokens, and LiveCodeBench v5 accuracy from 41.7% to 54.2% with 9.6% fewer response tokens. Adjusting the relative strengths of the anchor signals yields a strong empirical accuracy-efficiency Pareto frontier. These results establish Lightning Weave as a new practical route to efficient reasoning through capability composition.
Lightning Weave improves the accuracy-efficiency frontier of large reasoning models by composing capabilities from accuracy- and efficiency-oriented teachers into a single student through offline distillation.
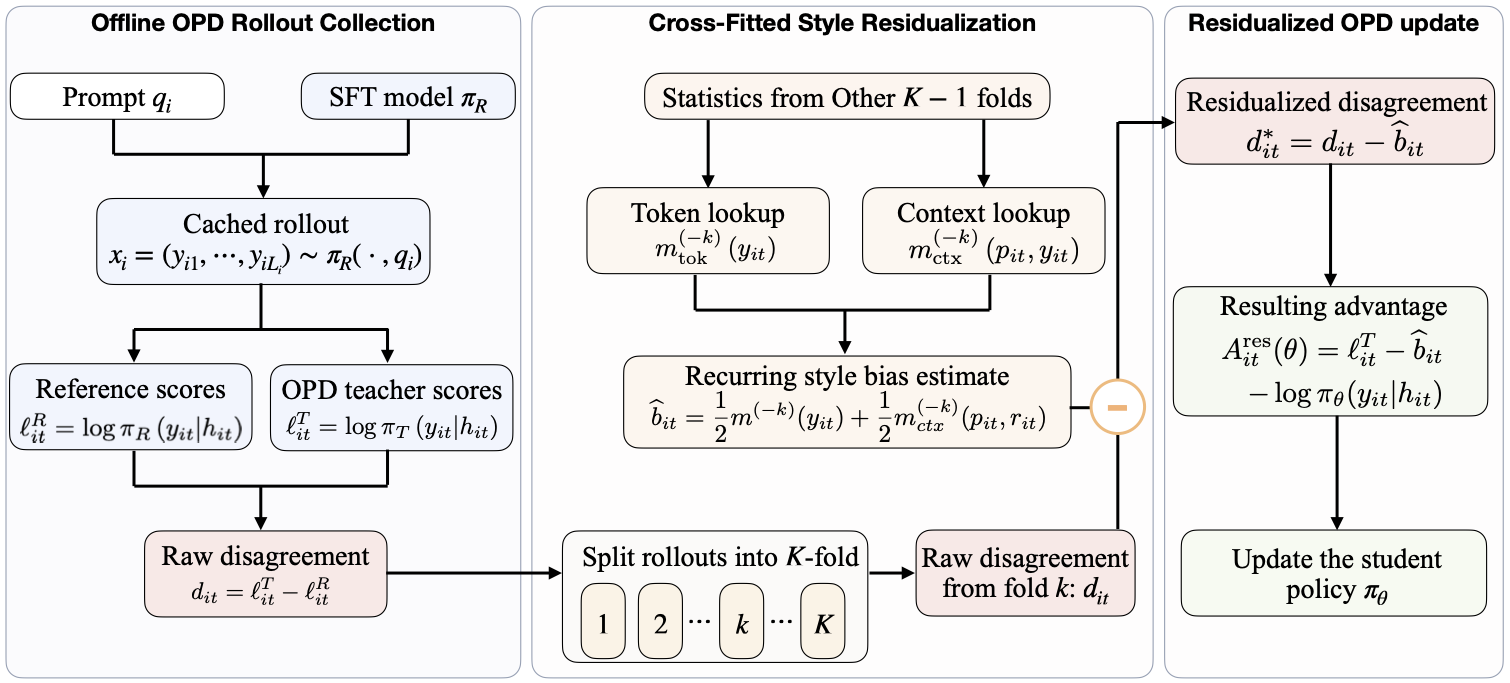
On-policy distillation (OPD) provides dense token-level supervision from a teacher, but its effectiveness can depend on teacher consistency, meaning that the model providing OPD supervision should also have generated the demonstrations used to train the supervised fine-tuning (SFT) reference. However, this condition is frequently violated in practice when SFT data have mixed or unknown provenance or when different models are preferred for SFT data generation and subsequent distillation. In such cross-teacher settings, even a stronger OPD teacher can yield little improvement over the SFT reference. We find that raw teacher--reference disagreement contains potentially useful context-specific teacher evidence as well as a recurring component associated with differences in wording, formatting, and reasoning cadence. We introduce Lightning OPD 2.0 with cross-fitted style residualization, which uses rollout-level cross-fitting to estimate this recurring component as an operational proxy for style-token bias and subtracts it before constructing the token-level OPD update. Across mathematical reasoning and code generation benchmarks, Lightning OPD 2.0 consistently outperforms Lightning OPD in cross-teacher settings. Starting from Klear-Reasoner-8B-SFT, Lightning OPD 2.0 reaches 82.4% on AIME 2024 and 63.0% on LiveCodeBench v5. Together, these results establish Lightning OPD 2.0 as a practical approach to cross-teacher OPD, relaxing teacher consistency as a prerequisite and allowing the SFT data generator and distillation teacher to be selected independently.
Lightning OPD 2.0 enables effective cross-teacher on-policy distillation by mitigating style bias through cross-fitted residualization, allowing the SFT data generator and distillation teacher to be chosen independently.
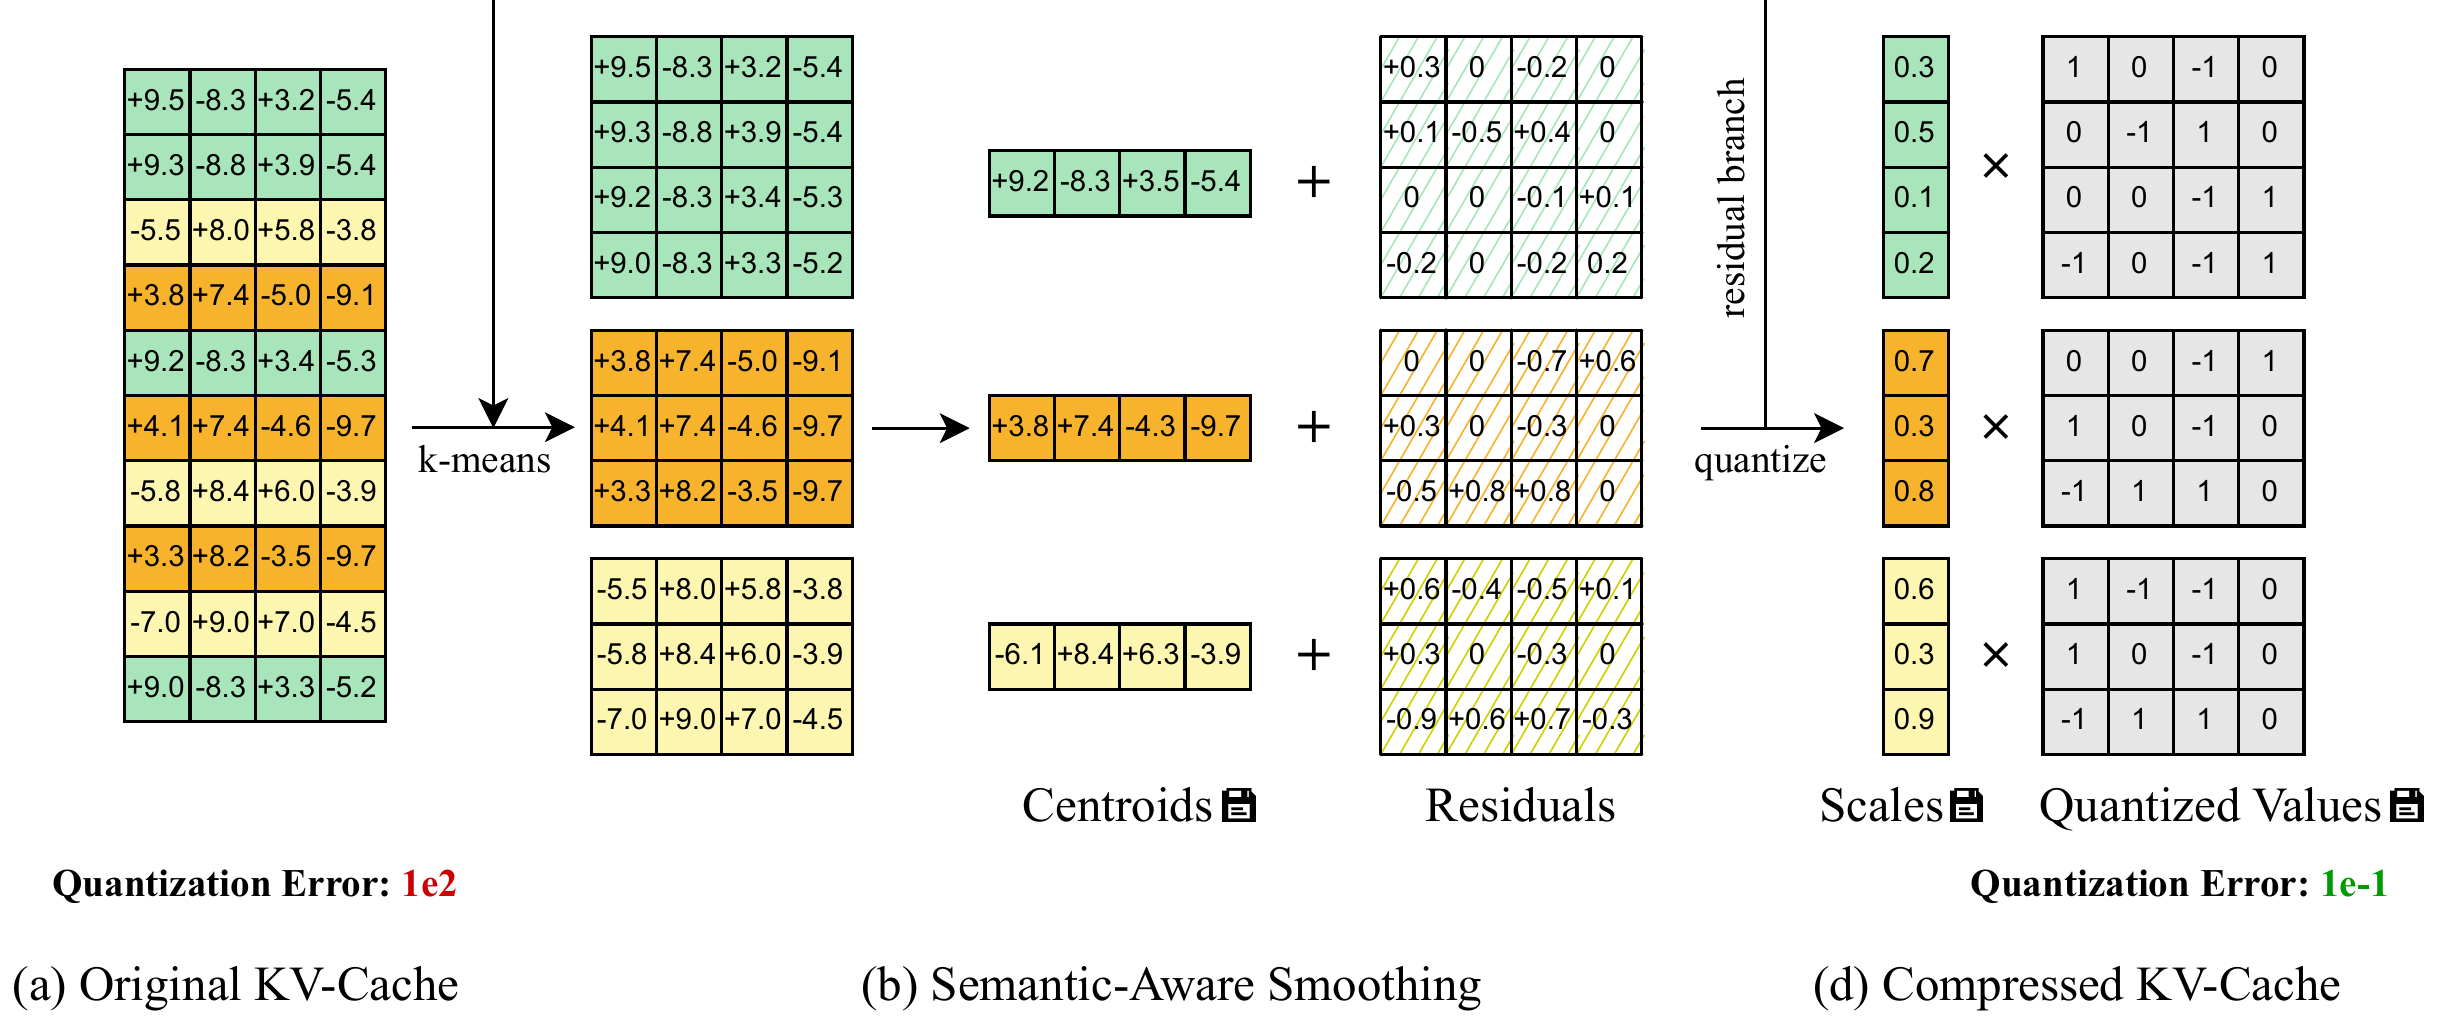
Despite rapid progress in auto-regressive video diffusion, we identify an emerging system–algorithm bottleneck that limits both deployability and capability: KV-cache memory. In auto-regressive video generation models, the KV-cache grows with history and rapidly dominates GPU memory (often ≥ 30 GB), blocking deployment on widely available hardware. More importantly, memory-bounded KV budgets force small working memory, which directly degrades long-horizon consistency in identity, layout, and motion, etc. To bridge this gap, we present Quant VideoGen (QVG), a training-free KV-cache quantization framework for auto-regressive video diffusion model. QVG exploits video’s spatiotemporal redundancy through Semantic-Aware Smoothing to produce low-magnitude, quantization-friendly residuals. QVG further propose Progressive Residual Quantization, a coarse-to-fine multi-stage scheme that reduces quantization error while enabling a smooth quality–memory trade-off. Across LongCat-Video, HY-WorldPlay, and Self-Forcing, QVG establishes a new Pareto quality-memory frontier, reducing KV memory by up to 7.0× with < 4% end-to-end latency overhead and significantly better quality over baselines.
A training-free KV-cache quantization framework for auto-regressive video diffusion, cutting KV memory by up to 7.0× with under 4% end-to-end latency overhead.
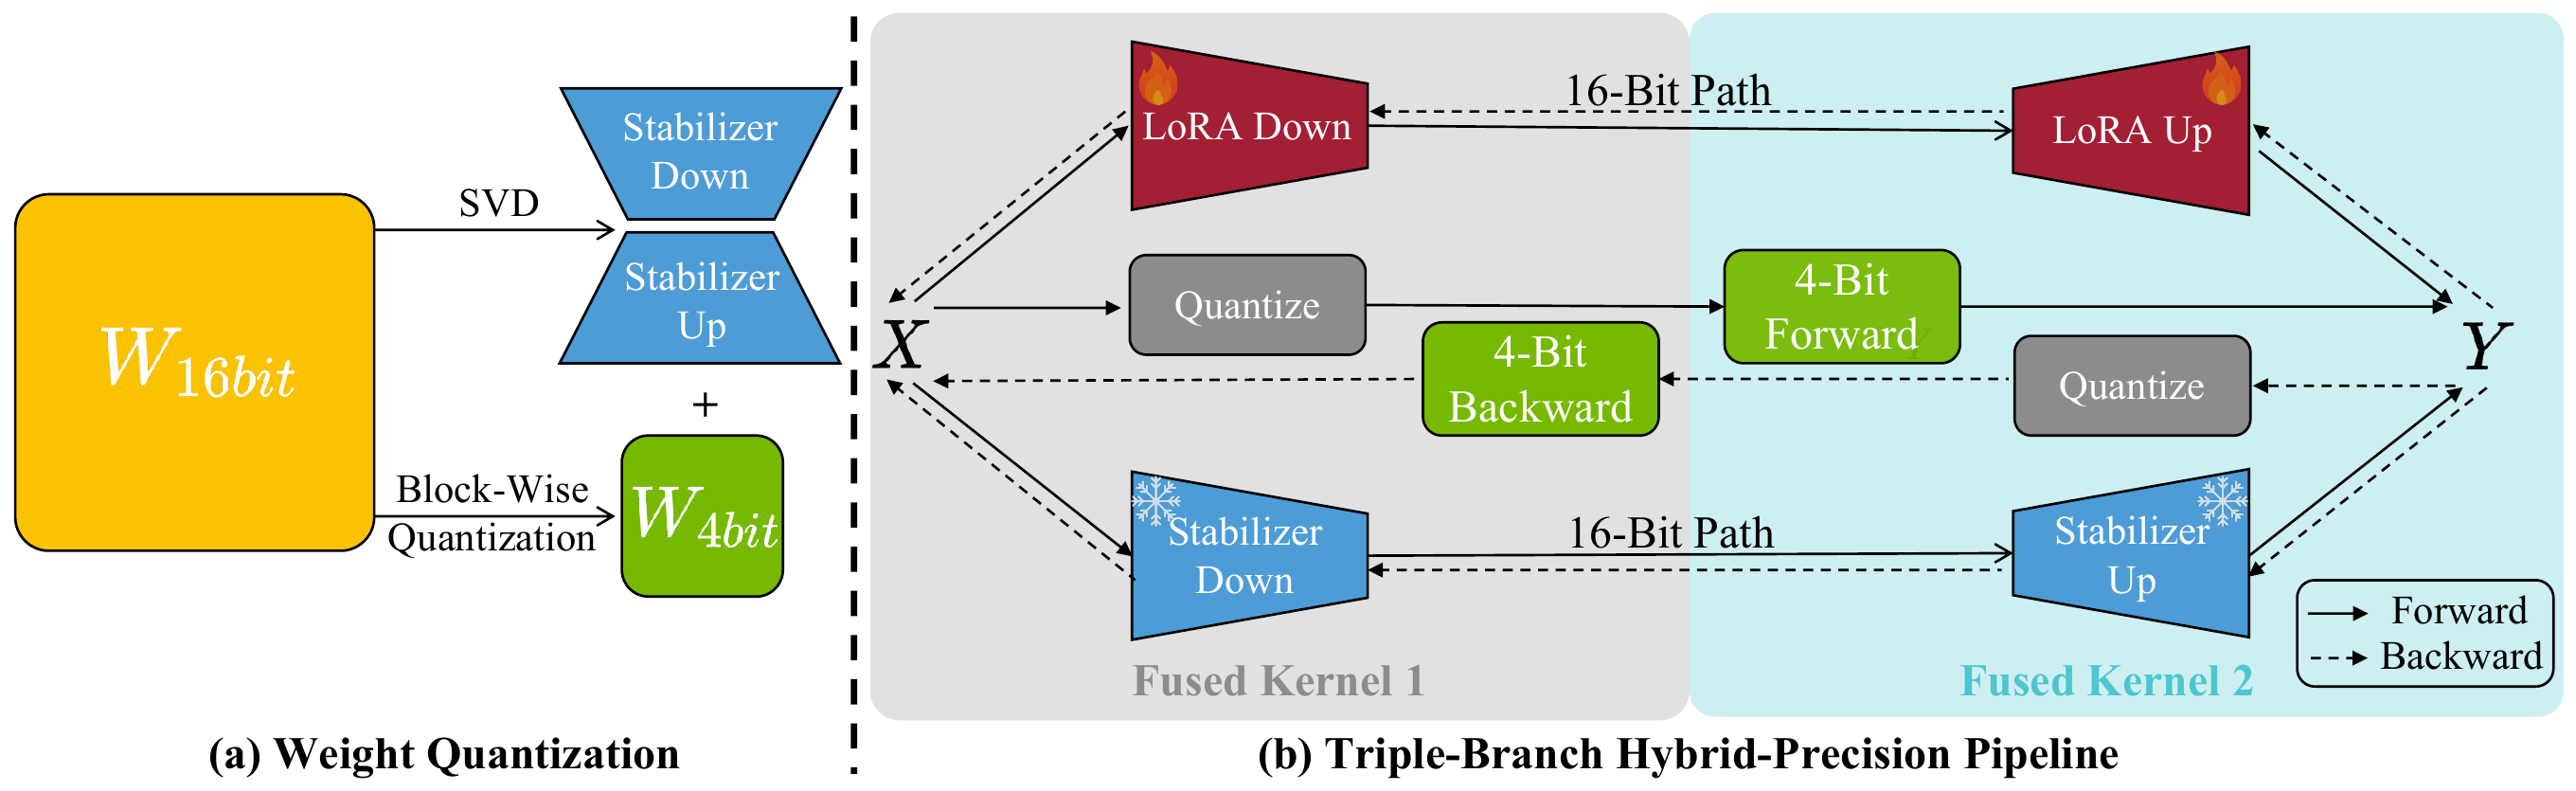
Diffusion models have become a dominant paradigm for high-quality generative modeling, while post-training is essential for adapting them to diverse downstream applications. However, post-training of large diffusion models is still challenging due to the prohibitive memory footprints and slow training speed, which existing parameter-efficient fine-tuning methods only partially address. To overcome these limitations, we propose FourTune, an efficient post-training framework for diffusion models based on an end-to-end W4A4G4 paradigm. FourTune introduces a triple-branch hybrid pipeline that augments the standard LoRA architecture with a frozen numerical stabilizer to isolate quantization-sensitive outliers, enabling stable training under native 4-bit computation. In addition, FourTune employs hardware-efficient block-wise quantization and customized fused kernels to support efficient quantized backpropagation and reduce memory bandwidth overhead. Across customization, reinforcement learning, and distillation tasks, FourTune matches the quality of full-precision fine-tuning. On FLUX.1-dev (12B), FourTune reduces memory overhead by 2.25× and increases end-to-end training throughput by 2.27× compared to BF16 LoRA.
An end-to-end W4A4G4 post-training framework for diffusion models, cutting memory 2.25× and boosting training throughput 2.27× over BF16 LoRA on FLUX.1-dev.


